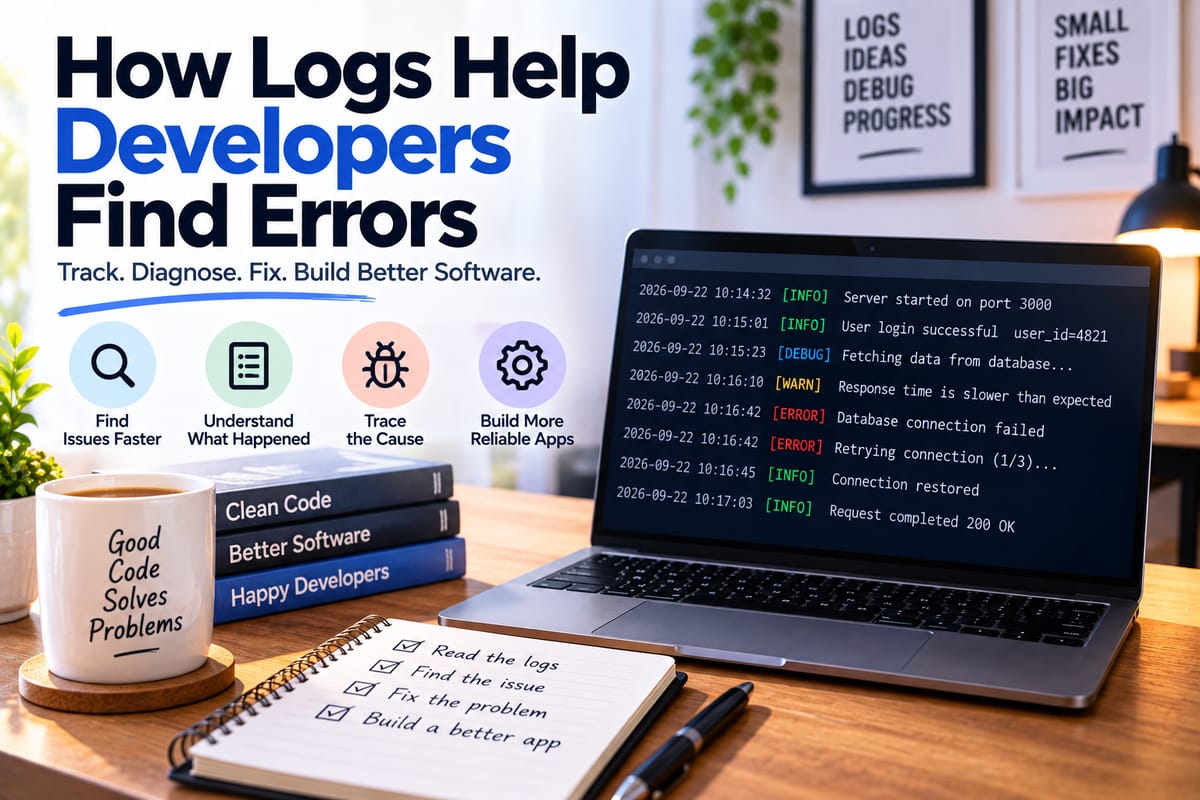
How Logs Help Developers Find Errors
Software can fail in ways that are not always obvious. An application might suddenly stop responding, return an unexpected result, reject a user's request, or slow down without showing a clear explanation. For developers, finding the cause of these problems can be much harder than noticing that something has gone wrong.
This is where software logs become valuable.
Logs record events that occur while an application, service, server, database, or other system is running. Depending on how they are configured, logs can show what happened, when it happened, which component was involved, and sometimes why the problem occurred.
For developers, this information can turn an otherwise confusing error into a traceable sequence of events.
Logs are therefore an important part of debugging, testing, monitoring, and maintaining software. They help development teams understand what applications are doing behind the scenes and provide evidence that can be used to investigate problems.
What Are Software Logs?
A software log is a recorded account of events that occur within a computer program or system.
An application might create a log entry when:
- A user signs in
- A database connection is established
- An API request is received
- A file is created
- A payment is processed
- A background task starts
- A configuration changes
- An unexpected condition occurs
- An exception is generated
- A service becomes unavailable
A simple log entry might contain information such as:
2026-09-22 10:15:42 ERROR Database connection failed
More sophisticated logs can contain considerably more information, including timestamps, application components, request identifiers, user or session identifiers where appropriate, error codes, and technical details about the event.
The purpose is not to record every possible detail without limitation. Instead, useful logging provides enough context to understand what an application was doing when something happened.
Why Logs Matter When Software Fails
An error message displayed to a user may be extremely general.
For example, a customer might see:
Something went wrong. Please try again.
That message may be appropriate for the user because exposing technical details could be confusing or unsafe. However, it does not tell a developer what actually happened.
A corresponding internal log might contain:
10:42:18 ERROR PaymentService
Request ID: 8f72a
Payment gateway timeout after 30 seconds
Endpoint: /payments/charge
The second record gives developers much more information.
They can determine that:
- The problem occurred in the payment service.
- The payment request reached the application.
- The application attempted to contact a payment gateway.
- The external service did not respond within the expected period.
- The request can be traced using its identifier.
This difference is one of the main reasons logs are so useful.
Logs Create a Timeline of Events
One of the biggest advantages of logging is that it creates a timeline.
Many software problems are not caused by one isolated event. Instead, several events may occur in sequence before the final failure.
Consider a web application that processes an order.
The logs might show:
09:31:02 INFO Order request received
09:31:02 INFO Order validated
09:31:03 INFO Inventory check started
09:31:03 INFO Inventory confirmed
09:31:03 INFO Payment request started
09:31:33 ERROR Payment request timed out
09:31:33 ERROR Order processing failed
Without logs, a developer might simply know that the order failed.
With logs, the sequence makes the problem easier to investigate.
The order was received successfully. Validation worked. Inventory was available. The failure occurred during payment processing.
That significantly narrows the search.
Common Types of Log Messages
Developers often organize logs according to the importance or severity of the event.
Debug Logs
Debug-level messages are generally used for detailed information that helps developers understand application behavior.
They might record:
- Variable states
- Function execution
- Configuration values
- Processing steps
- API request details
- Database operations
Debug logging can be extremely useful during development, but producing too much information in a production environment can make logs difficult to analyze.
Informational Logs
Information-level messages describe normal application activity.
For example:
INFO User authentication completed
or:
INFO Background synchronization started
These messages help developers understand what the system is doing when everything is operating normally.
Warning Logs
Warnings indicate something unusual that may not have caused an immediate failure.
For example:
WARNING API response exceeded expected processing time
A warning might identify a developing problem before it becomes a serious error.
Error Logs
Error messages indicate that something went wrong while processing an operation.
Examples include:
ERROR Unable to connect to database
or:
ERROR File upload failed
Error logs are particularly useful during incident investigation because they identify events that require attention.
Critical or Fatal Logs
Some systems use critical or fatal levels for severe failures that prevent important parts of the application from operating.
For example:
CRITICAL Application startup failed
These events may require immediate investigation.
How Developers Use Logs to Trace Errors
Finding an error is rarely as simple as searching for the word ERROR.
Developers typically combine multiple pieces of information.
1. Identify When the Problem Occurred
The timestamp provides an important starting point.
If users report that a service stopped working at 2:15 PM, developers can examine events around that period.
This helps reduce the amount of information they need to inspect.
2. Find the Relevant Component
Modern applications are often made up of multiple components.
A problem could originate in:
- The frontend
- Backend services
- Authentication
- Databases
- APIs
- File storage
- Messaging systems
- External services
Logs can reveal which component generated the relevant event.
3. Follow the Sequence
Developers can examine what happened immediately before and after an error.
For example:
Request received
Authentication successful
Database query started
Database query failed
Response returned with error
This sequence provides a much clearer picture than looking at the final error alone.
4. Compare Successful and Failed Requests
Developers can sometimes compare logs from a successful transaction with logs from a failed transaction.
Suppose both requests follow the same path until one reaches a different database operation.
That difference could provide an important clue.
5. Trace Related Events
Modern applications often assign identifiers to requests or transactions.
For example:
Request ID: 74ac92
Developers can use that identifier to find related events across multiple services.
This is particularly valuable in distributed systems where a single user action can generate activity across several components.
Logs and Debugging Work Together
Logging does not replace debugging.
Instead, it provides information that helps developers determine where to investigate.
The broader process of finding, diagnosing, and fixing software problems involves multiple techniques. The What Debugging Is and How Developers Find, Diagnose and Fix Software Problems guide explores that process in greater detail.
A developer might use logs to identify the failing component and then reproduce the problem locally.
For example:
Log: Database query fails when processing a particular request.
Debugging: Developer reproduces the request and examines the database interaction.
Investigation: Developer discovers that a specific input creates an invalid query parameter.
Fix: Code is changed to validate the input correctly.
Testing: The fix is tested against the original problem and related scenarios.
Logs are therefore one piece of a much larger debugging workflow.
How Logs Help With Application Errors
Different types of software errors leave different patterns in logs.
Configuration Errors
An application might fail because an environment variable is missing or a configuration value is incorrect.
A log could reveal:
ERROR Required database configuration not found
This points the developer toward configuration rather than application logic.
Database Errors
Database-related logs may reveal:
- Connection failures
- Authentication problems
- Query errors
- Timeouts
- Missing tables
- Constraint violations
- Transaction failures
These details can help developers determine whether the problem originates in application code, the database, or communication between the two.
API Errors
Applications frequently communicate with external services through APIs.
Logs can help show:
- Which endpoint was contacted
- When the request was sent
- Whether a response was received
- What status code was returned
- Whether a timeout occurred
This can distinguish an application problem from an external service problem.
Authentication Errors
Authentication logs can help identify issues involving:
- Invalid credentials
- Expired sessions
- Failed token validation
- Permission problems
- Misconfigured authentication services
Care must be taken not to log passwords, authentication tokens, or other sensitive information.
Logs Can Help Identify Patterns
Some errors happen only once.
Others occur repeatedly.
A single error might be difficult to interpret, but thousands of similar errors can reveal a pattern.
Suppose an application records:
ERROR Database timeout
once every few days.
That may require a different investigation from an application generating thousands of database timeout errors every hour.
Patterns can reveal:
- Performance bottlenecks
- Traffic-related problems
- Recurring configuration issues
- Resource shortages
- Failing dependencies
- Specific user workflows associated with errors
This makes logs valuable not only for individual debugging sessions but also for understanding long-term system behavior.
Logs and Software Testing
Logging can also support software testing.
During testing, developers may need to verify that a program behaves correctly under different conditions.
The What Is Software Testing and How Do Developers Ensure Software Quality? guide provides broader context on how testing is used to identify defects and improve software quality.
Logs can help testers and developers understand what happened during a test.
For example, a test may verify that an application correctly handles an unavailable database.
The expected behavior could be:
- Database connection fails.
- Application records an error.
- Application does not crash unexpectedly.
- User receives an appropriate response.
- System continues operating where possible.
Logs provide evidence about whether the expected sequence occurred.
Logging Across Modern Software Architectures
A simple application may have one log file.
Modern applications can be much more complicated.
A single user action might involve:
Browser → Web server → Application service → Authentication service → Database → External API
Each component may generate its own logs.
This creates a challenge: developers need to connect events across different systems.
Understanding how applications are divided into components helps explain why this matters. The How Software Architecture Organizes Applications guide examines how different software components are structured and how they work together.
In a distributed application, centralized logging and request tracing can make it much easier to follow an event across multiple services.
Centralized Logging
When applications run across multiple servers or services, developers may not want to manually inspect individual machines.
Centralized logging collects information from different sources into a common system.
This can allow developers to search for:
- Error messages
- Request IDs
- Service names
- Timestamps
- User actions
- Status codes
- Performance problems
For example, if a request moves through five services, a centralized logging platform can help developers locate related events from each service.
This can significantly reduce investigation time.
Structured Logging
Traditional logs are sometimes written as plain text.
For example:
2026-09-22 14:20:11 ERROR User registration failed
Structured logging stores information in a consistent format, often using JSON.
For example:
{
"timestamp": "2026-09-22T14:20:11Z",
"level": "error",
"service": "registration",
"event": "registration_failed",
"request_id": "74ac92"
}
The structured format makes it easier for software tools to search, filter, group, and analyze events.
A development team could search for every error generated by the registration service during a specific period without manually reading thousands of lines.
Good Logging Requires Useful Context
A log message should provide enough information to be useful.
Compare these two examples:
ERROR Failed
and:
ERROR Invoice generation failed: customer record unavailable
The second message provides much more context.
Useful log entries may include:
- What happened
- Where it happened
- When it happened
- Which operation was being performed
- A relevant error code
- A request or transaction identifier
- The affected component
At the same time, developers should avoid filling logs with unnecessary information.
The goal is useful context, not maximum volume.
What Developers Should Avoid Logging
Logging everything can create its own problems.
Developers need to be particularly careful with sensitive information.
Applications should generally avoid placing information such as:
- Passwords
- Authentication tokens
- Private encryption keys
- Full payment card details
- Sensitive personal information
- Confidential business information
into ordinary logs.
Logs can be accessed by development, operations, security, and support teams, making appropriate access controls important.
A well-designed logging strategy balances diagnostic usefulness with privacy and security.
Log Rotation and Storage
Applications can generate enormous amounts of log data.
If logs are stored indefinitely without management, they can consume significant storage capacity.
Organizations therefore often use log retention and rotation policies.
Older logs may be:
- Archived
- Compressed
- Deleted after a defined period
- Moved to lower-cost storage
- Retained longer when required for operational or regulatory reasons
The appropriate retention period depends on the organization's needs, the type of data involved, security requirements, and applicable regulations.
Logs Can Help Detect Problems Before Users Report Them
Logging becomes even more powerful when combined with monitoring and alerting.
Instead of waiting for someone to report a failure, a monitoring system can detect unusual patterns in application logs.
For example, an alert could be triggered when:
- Error rates suddenly increase
- Database connections repeatedly fail
- API timeouts exceed a threshold
- Authentication failures spike
- A critical service stops responding
This changes logging from a passive record into part of an active operational process.
Developers and operations teams can investigate problems while they are occurring rather than relying entirely on customer reports.
Logs as a Record of Application Behavior
Software changes constantly.
Developers add features, fix bugs, change dependencies, improve performance, and modify infrastructure.
Logs provide a historical record that can help teams understand how the system behaved during different periods.
When an issue appears after a deployment, developers can compare activity before and after the change.
This can help answer questions such as:
- Did the error exist before the release?
- Did its frequency increase afterward?
- Which service started producing the errors?
- Did response times change?
- Did a particular workflow become more likely to fail?
That historical perspective can be extremely valuable when investigating complex problems.
How Logs Fit Into the Software Development Process
Logging is not an isolated activity performed only after something breaks.
It can be incorporated throughout the software lifecycle.
During development, logs help developers understand application behavior.
During testing, they provide information about test execution and failures.
During deployment, they can reveal configuration or infrastructure problems.
During production, they support monitoring, troubleshooting, and incident investigation.
During maintenance, historical logs can help teams understand recurring issues.
This makes logging part of a broader development and maintenance discipline. The Complete Guide to Software Development Processes provides a broader view of how different activities fit together throughout the software lifecycle.
A Practical Example of Log-Based Error Investigation
Consider an online shopping application where customers report that checkout sometimes fails.
A developer starts by examining the logs around failed checkout attempts.
They discover:
15:42:08 INFO Checkout started
15:42:08 INFO Cart validated
15:42:09 INFO Inventory confirmed
15:42:09 INFO Payment request submitted
15:42:39 ERROR Payment gateway timeout
15:42:39 ERROR Checkout failed
The logs show that the shopping cart and inventory systems were working.
The payment request was submitted, but the external payment gateway did not respond within the expected time.
The developer then examines other failed transactions and discovers that similar timeouts are occurring repeatedly.
The investigation can now focus on the payment integration, network communication, timeout configuration, or external service rather than the entire checkout application.
That is the practical value of logging: it reduces uncertainty.
Making Logs More Useful for Developers
A strong logging strategy should be intentional.
Developers can improve the usefulness of logs by:
- Using consistent log levels
- Including timestamps
- Adding meaningful context
- Using request or transaction identifiers
- Avoiding sensitive information
- Using structured formats where appropriate
- Centralizing logs for distributed systems
- Establishing retention policies
- Monitoring error patterns
- Reviewing logs during testing
- Documenting important logging conventions
The objective is to make it possible for another developer to understand what happened without having to reconstruct the entire application from scratch.
Turning Application Events Into Actionable Information
Logs are essentially a history of what software has been doing.
On their own, they are simply records. Their real value comes from how developers use those records to investigate behavior, identify patterns, reproduce failures, and make informed changes.
A well-designed logging system can show the path leading to an error, identify the component involved, connect related events, and provide evidence about whether a fix has actually improved the situation.
As applications become more distributed and complex, that visibility becomes increasingly important. Developers cannot always watch every process directly, but well-designed logs can provide a detailed window into what is happening inside the software.
When logs are combined with debugging, testing, monitoring, and thoughtful software architecture, they become much more than error messages. They become an essential tool for understanding software, diagnosing problems, and keeping applications reliable over time.